智能信息采集器软件开发实践
2021-06-16傅骏傅馨竹吴高静丁才愈龙辉阳熊子淇
傅骏 傅馨竹 吴高静 丁才愈 龙辉阳 熊子淇

The Software Development Practice of Intelligent Information Collector
FU Jun1, FU Xin-zhu2, WU Gao-jing1, DING Cai-yu1, LONG Hui-yang1, XIONG Zi-qi1
(1.Department of Materials Engineering, Sichuan Engineering Technical College, Deyang 618000, China;
2.Junior Middle School, Deyang No.5 Middle School, Deyang 618000, China)
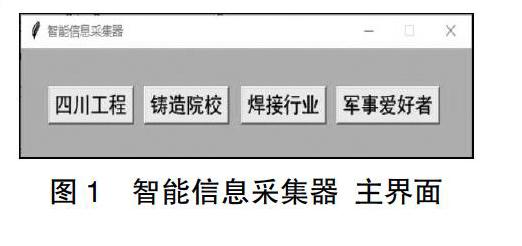
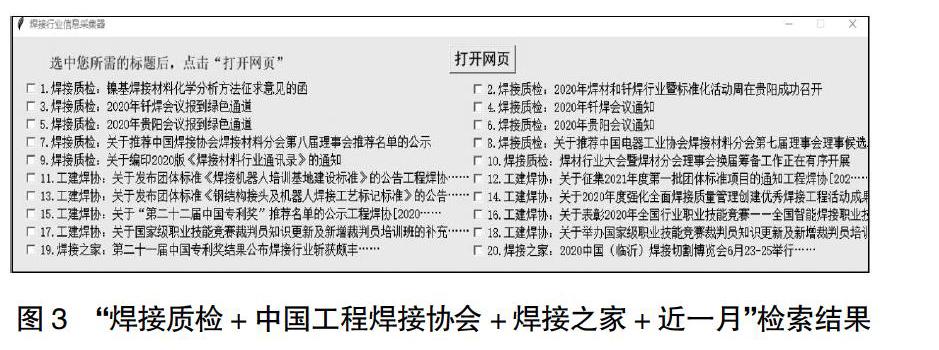
【摘 要】应用爬虫技术开发的智能信息采集器,可以帮助用户及时获得工程学院、铸造院校、焊接行业、军事网站的最新消息。论文选用tkinter进行界面设计,应用python爬虫技术对xpath、抓取到的日期、网址进行了处理,顺利实现抓取消息并获得消息的网址。用户可以进一步打开感兴趣的网页进行详细阅读。
【Abstract】The intelligent information collector developed with crawler technology can help users get the latest information of Engineering College, Foundry College, welding industry and military websites in time. The paper selects and uses tkinter to design the interface, and uses python crawler technology to process the xpath, the fetched date, and the URL, which smoothly realized fetching the message and getting the URL of the message. Users can further open the web pages of interest for detailed reading.
【關键词】爬虫技术;信息采集;python;二次开发;xpath
【Keywords】crawler technology; information collection; python; secondary development; xpath
【中图分类号】TP311.5 【文献标志码】A 【文章编号】1673-1069(2021)05-0192-02
1 引言
网络信息时代,资讯铺天盖地、纷繁复杂。科学院所、行业企业和政府部门需要知道最新的科学前沿、法律法规和工作动态的网页信息,从而作出决策。但冗杂的网页信息在他们查找时是很困难的。本团队在完成省级课题“厉害了,我的国——建国以来重大科技成就科普作品”过程中经常需要紧跟科技成果和技术发展,这就要对指定的相关度高的网站进行消息搜索。如果逐一搜索这些网站的栏目,花费时间长并且经常容易遗漏,团队基于python爬虫技术设计了“智能信息采集器”,有效解决了这一问题。
2 技术基础
2.1 python
网络爬虫按照一定的规则,自动地抓取万维网信息,可以采集所有其能够访问到的页面内容,以获取或更新这些网站的内容和检索方式。获取网页消息,目前技术手段有python爬虫技术以及各种爬虫框架,本团队采用python爬虫技术进行设计。tkinter模块是python的标准GUI工具包接口,可以非常方便实现很多直观的功能。tkinter是python自带库,不需下载安装,可直接使用[1]。……
