大数据平台下实时电影推荐算法研究
2021-09-13牛路帅彭龑
牛路帅 彭龑

摘 要:随着互联网数据量的不断扩大,数据的实时推荐需求已经不能被传统的推荐模型所满足,协同过滤推荐算法的不足也越来越明显。为此,通过大数据计算框架Spark平台构建基于模型的推荐算法来更好地应对海量数据实时推荐的问题。首先,通过预先设定的计算方法进行模型的构建;同时将一种改进的余弦相似度算法应用到模型中,不仅可以缩短推荐实现的时间,而且可以提高推荐性能。实验结果表明,该算法和传统协同过滤算法相比,提高了准确率和时效性,验证了系统可较好地满足用户的实时需求。
关键词:Spark;实时;推荐算法;协同过滤
中图分类号:TP399 文献标识码:A
文章编号:2096-1472(2021)-09-13-04
Abstract: With the continuous expansion of the amount of Internet data, traditional recommendation model can no longer meet the demand for real-time recommendation. The deficiency of collaborative filtering recommendation algorithm is becoming more and more obvious. For this reason, this paper proposes to build a model-based recommendation algorithm based on the Spark platform of big data computing framework, in order to better deal with the problem of real-time recommendation of massive data. First of all, the model is constructed through the preset calculation method, and an improved cosine similarity algorithm is applied to the model, which can not only shorten the time of recommendation implementation, but also improve the performance of recommendation. Experimental results show that compared with the traditional collaborative filtering algorithm, the proposed algorithm improves the accuracy and timeliness, and verifies that the system can better meet the real-time needs of users.
Keywords: Spark; real time; recommendation algorithm; collaborative filtering
1 引言(Introduction)
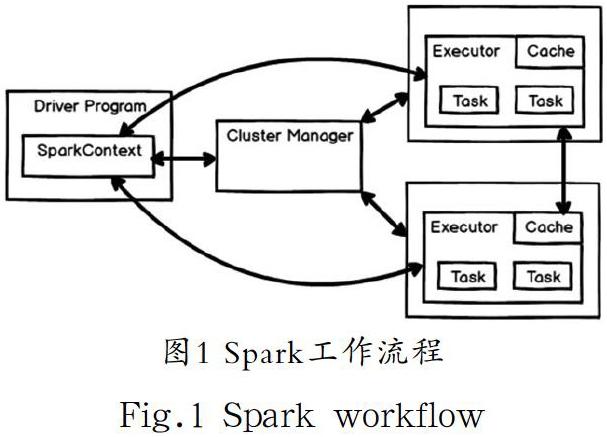
在信息爆炸的今天,信息超載的问题[1]逐渐显现出来,人们有许多种方式和途径去获取信息,但是很难从这些信息中找到自己所感兴趣的东西。推荐系统则是解决这个问题的关键所在[2-4]。推荐系统能够通过分析用户的兴趣和行为,智能地向用户推荐所需信息,其既需要筛选出大量有用的数据,又要实时地满足用户的个性化需求[5],所以大数据处理是推荐系统所要具有的能力[6-7]。Spark是一种具有大数据处理能力的内存计算框架[8],运行于Spark平台的推荐系统可以发挥更高的处理能力。本文旨在利用Spark平台对基于模型的推荐算法进行优化与并行化实现,和传统的推荐算法相比,实时性与准确性也都有较大的提高。
2 Spark分布式计算框架(Spark distributed computing framework)
2.1 Spark运行架构原理