基于信息距离的文献个性化知识发现系统的设计与实现
2021-08-23刘爱琴刘扬
刘爱琴 刘扬
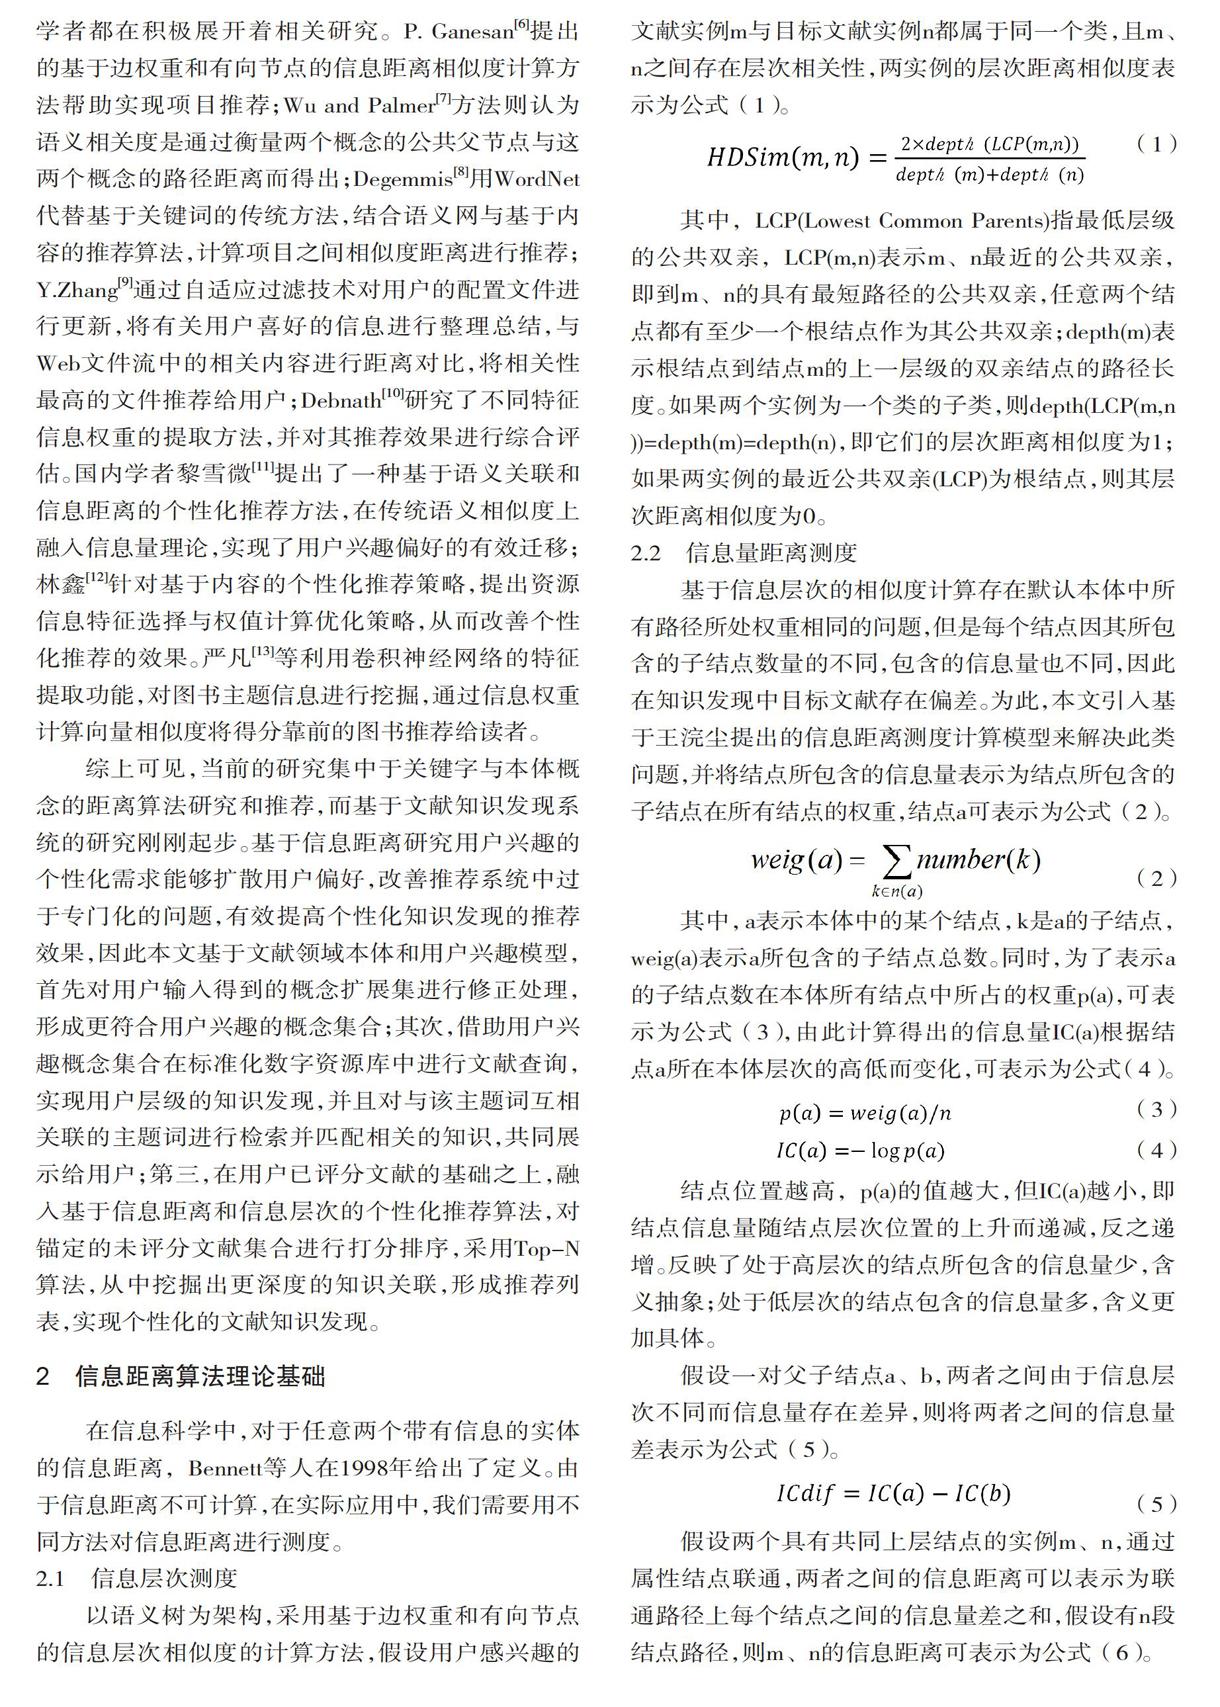
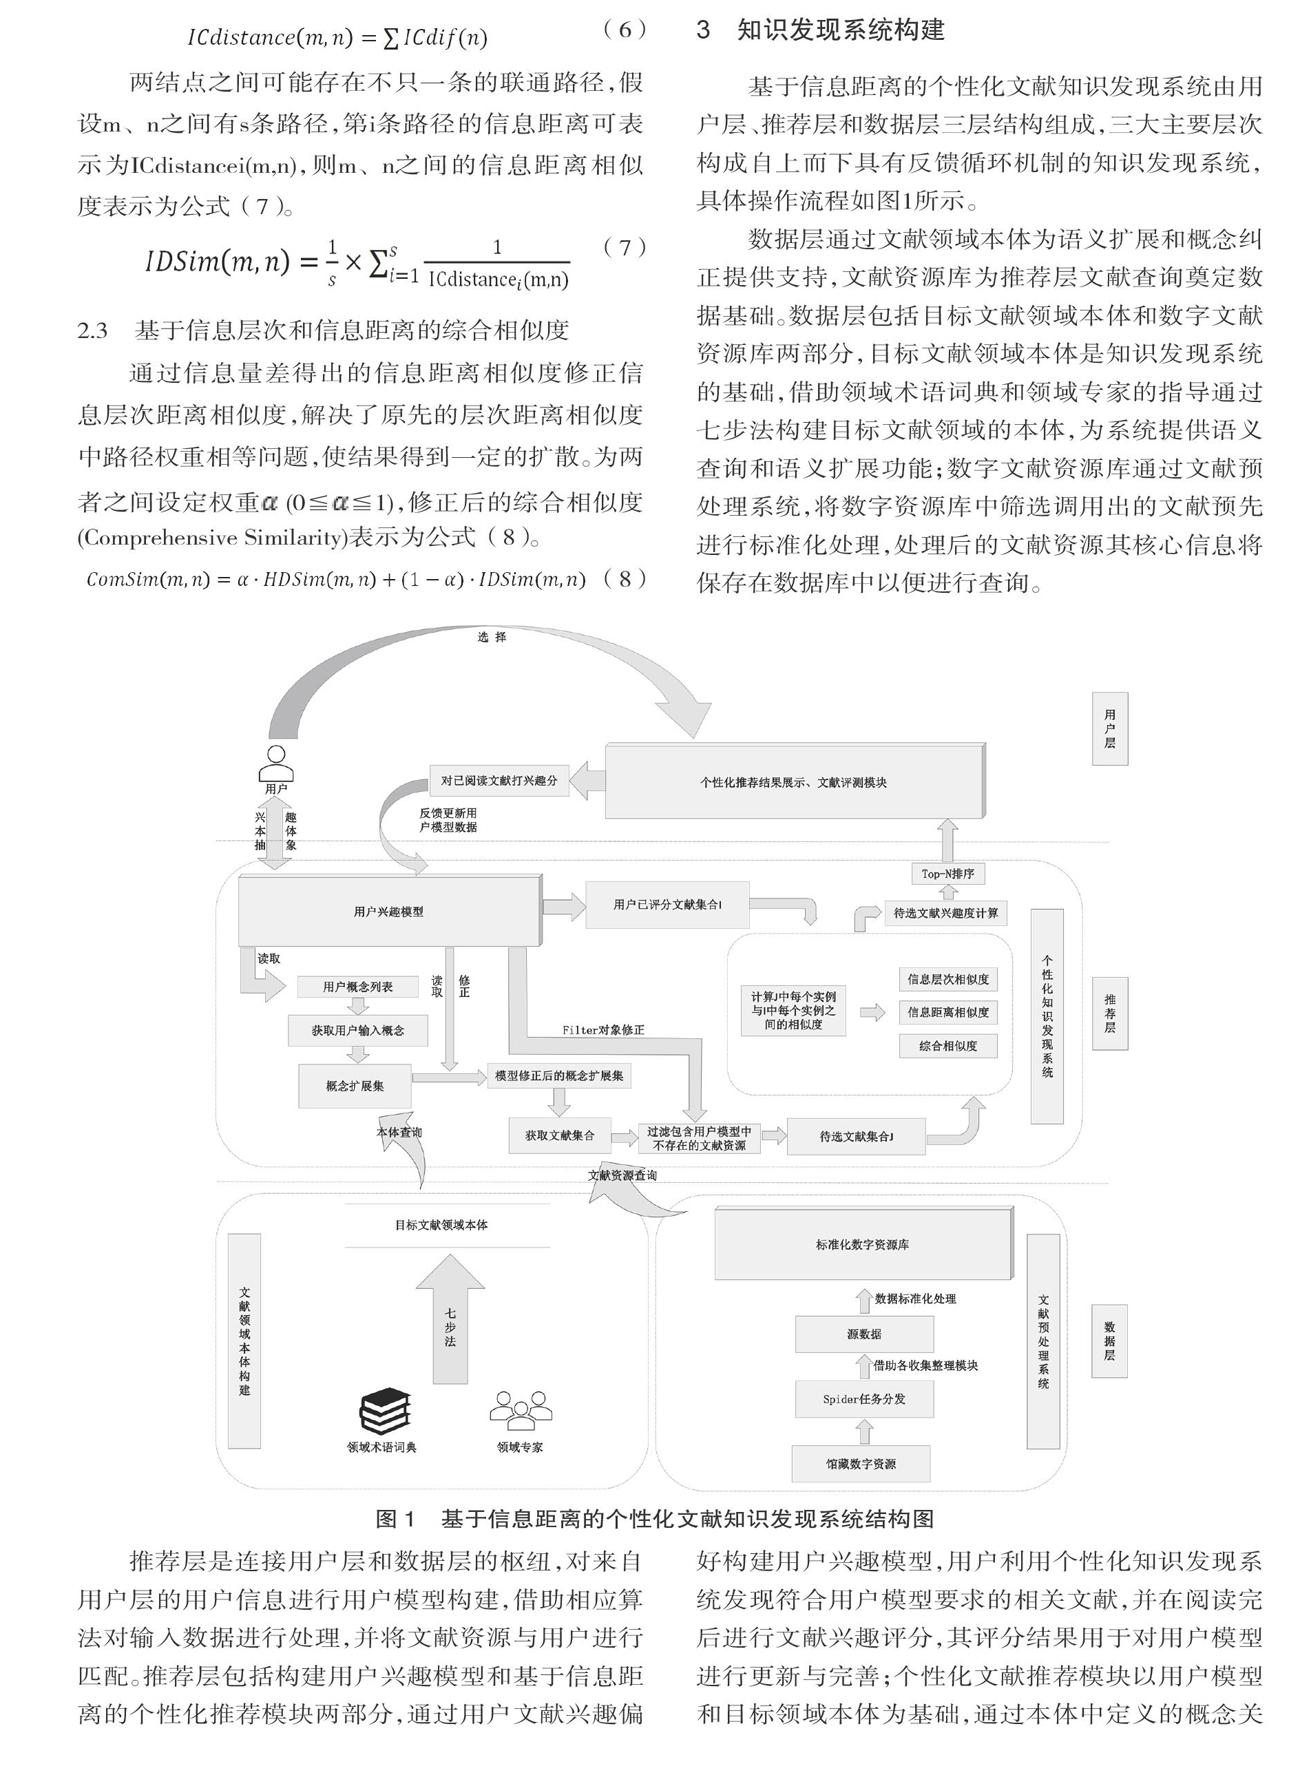

摘 要 本文基于信息距离的文献个性化知识发现系统,首先基于文献领域本体对用户输入得到的概念扩展集进行修正处理,形成更符合用户兴趣的概念集合;其次,借助兴趣概念集合,将主题词和与其互相关联的知识匹配,实现用户层级的知识发现;最后,融入基于信息距离和信息层次的个性化推荐算法,对锚定的未评分文献集合进行打分排序,采用Top-N算法,从中挖掘出更深度的知识关联,形成推荐列表,实现个性化的文献知识发现。该系统一方面改善了基于内容的知识发现系统中结果过于专一化和延展性差等问题,扩展了查询粒度;另一方面通过信息量权重的引入,在提高知识检索效率和知识推荐准确度的同时,实现了更为精准的个性化知识发现。
关键词 信息距离 兴趣概念集合 文献个性化 知识发现系统
分类号 G251.6
DOI 10.16810/j.cnki.1672-514X.2021.07.010
Design and Implementation of Personalized Knowledge Discovery System Based on Information Distance
Liu Aiqin, Liu Yang
Abstract Based on the literature personalized knowledge discovery system of information distance, this paper corrects the concept extension set obtained by the user based on the literature domain ontology, and forms a collection of concepts that more in line with the users interest. Secondly, with a collection of interest concepts, matching subject words and interrelated knowledge to achieve knowledge discovery at the user level. Finally, the personalized recommendation algorithm based on information distance and information level is integrated to rank the collection of unscored literature, and the Top-N algorithm is used to excavate the deeper knowledge correlation, form the recommendation list and realize the personalized literature knowledge discovery. On the one hand, the system improves the problems of excessive specialization and poor elongation of the results in the content-based knowledge discovery system, expands the granularity of query. On the other hand, with the help of information content, it can realize more accurate personalized knowledge discovery while improving the efficiency of knowledge retrieval and the accuracy of knowledge recommendation.
KeywordsInformation distance. Collection of interest concepts. Literature personalization. The knowledge discovery system.
1 研究背景
由于用户信息服务的重点和难点正从文献获取转变为知识发现[1],因此打破以往的书刊目录、文献索引和部分文献全文利用的局限,引入知识挖掘、索引规则构建信息资源的立体知识网络[2],为用户提供具有完善、高效的知识挖掘与数据分析功能的知识发现系统[3]迫在眉睫。
发现系统经历了传统资源发现、学术资源发现和知识发现三个阶段。第一阶段,全球第一个资源发现系统Summon,其重点放在资源发现功能上,信息服务体系未能形成。第二阶段,发现系统从出版商、内容商、大学、公开网站等提取各类有价值的数据信息资源[4],实现了资源获取。……