基于公共词集对长篇小说相似度的研究
2018-12-21郭涛霸元婕李绍昂
郭涛 霸元婕 李绍昂
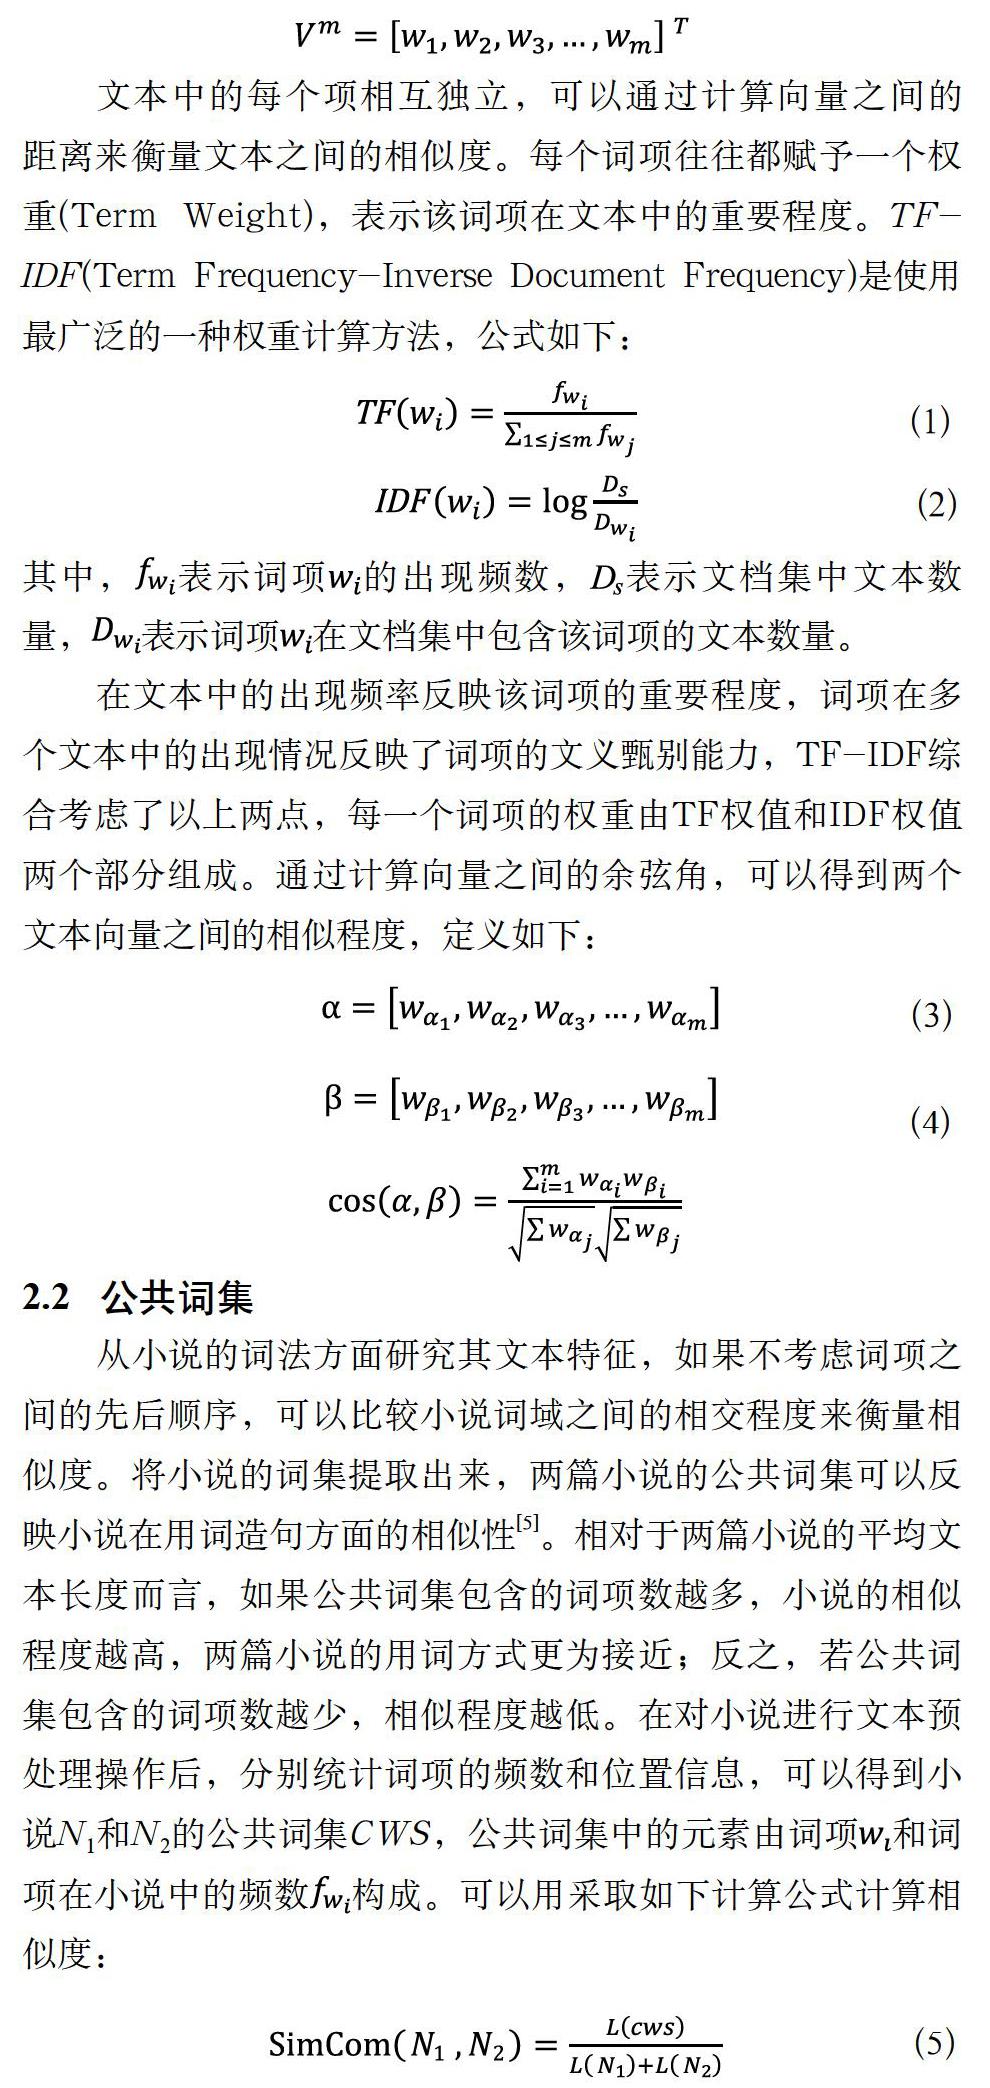
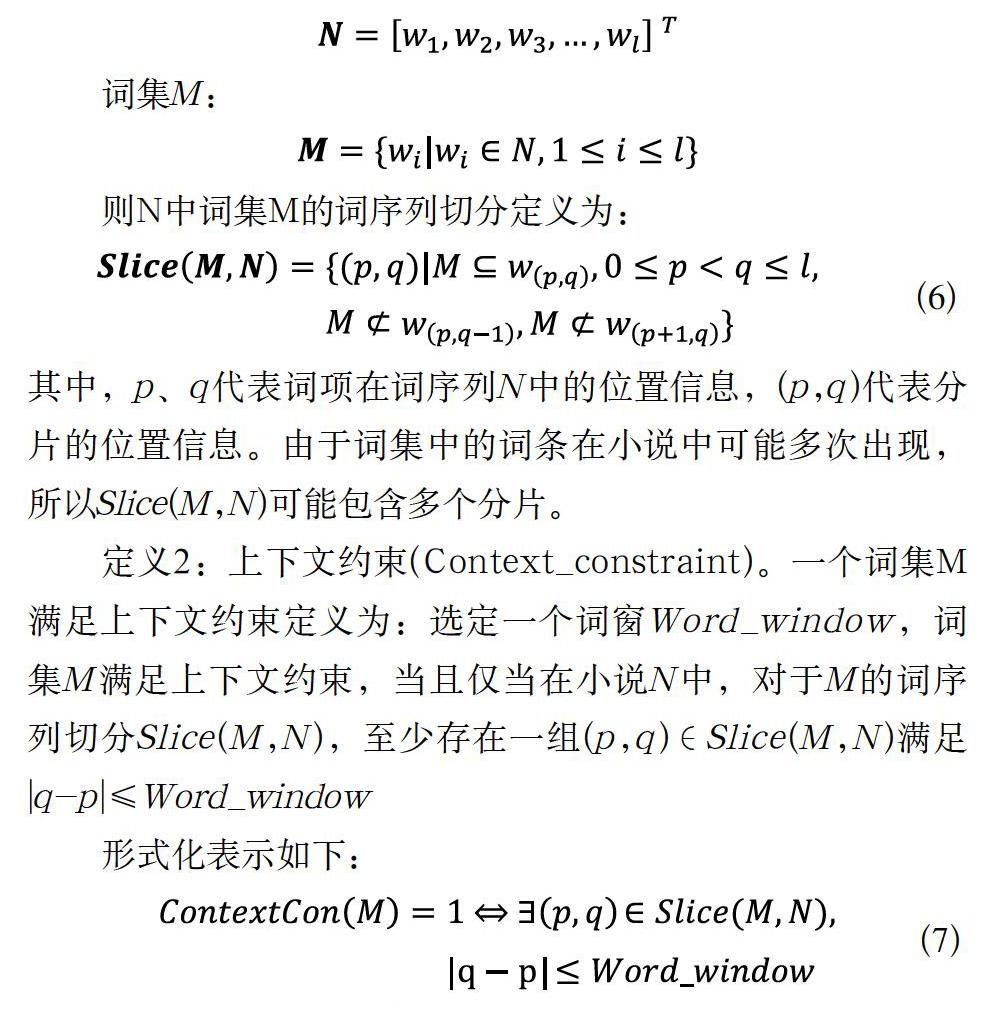
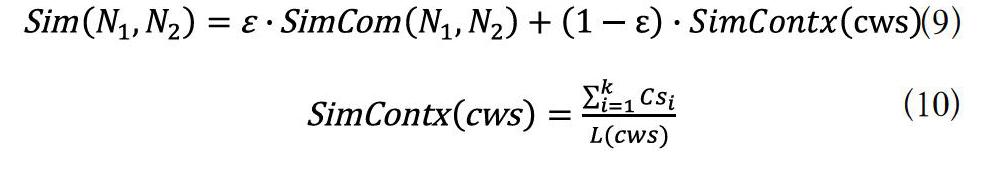
摘 要:传统的文本相似度计算基于向量空间模型(VSM),文本映射成独立的、互不关联的词构成的向量。由于长篇小说具有比普通文本更为复杂的构成元素,以及更加紧密的上下文联系,传统算法忽略词项的上下文联系,并且产生高维向量,因此算法的效率和精度不理想。为此,本文基于公共词集对长篇小说进行相似度计算,并对公共词集进行上下文约束检查,得到关联比较紧密的词集,作为小说的主要特征。实验结果表明,对于某些小说类型,效果有很大的提升。
关键词:公共词集;小说相似度;上下文约束
中图分类号:TP391.1 文献标识码:A
Abstract:Traditional text similarity computation is based on Vector Space Model (VSM),where the text is mapped into independent and unrelated words.Because novels have more complex elements and much closer context than ordinary texts,the traditional algorithm ignores the context of the words and produces the high dimensional vector,so that the efficiency and accuracy of the algorithm are not ideal.For this reason,this paper calculates the similarity of the novels based on the common word set,and carries out the context constraint check on the common word set to achieve a more closely related word set as the main feature of the novel.The experimental results show that for some types of novels,the effect is greatly improved.
Keywords:common word set;novel similarity;context constraint
1 引言(Introduction)
随着互联网技术的发展,网络上的文本数据呈现爆炸式增长,文本处理算法的相关研究也随之发展起来。其中,文本相似度计算成为热点研究方向,其目的在于建立一个合理的衡量模型,对文本间的相似程度进行量化。小说作为一种文学作品,与普通文本有较大区别,小说的构成要素要比普通文本复杂很多,比如时间、地点、人物、社会、环境等等,并且小说的上下段落、上下情节之间联系十分紧密。所以,必须要从新的角度建立小说相似度的衡量模型。
目前经典的文本相似度计算算法大部分基于向量空间模型(VSM)[1]。向量空间模型将文本视作由独立的、互不关联的词构成的一个向量,并且把词语在文中出现的频数作为文本的主要特征。通过将文本映射成一个向量模型,文本相似度计算也就转换成向量之间的相似度计算。……
