多策略融合的俄语文本词语提取方法研究
2021-08-06唐菊香孙怿晖廖晓刘建国于娟
唐菊香 孙怿晖 廖晓 刘建国 于娟
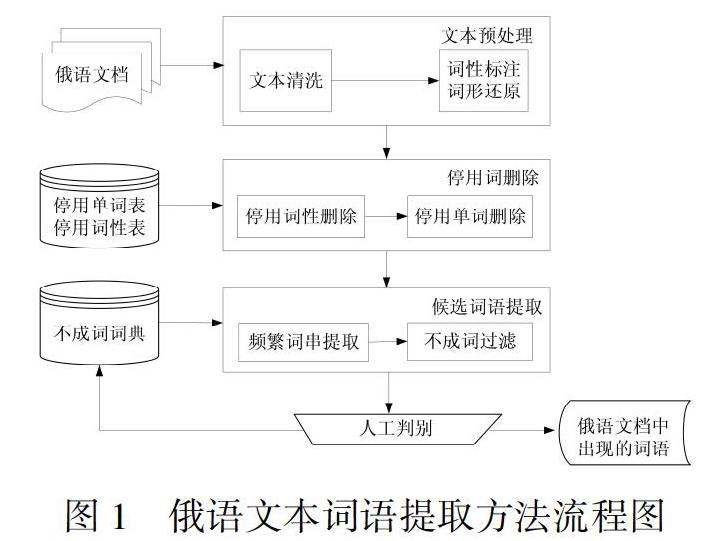
摘 要:俄语是联合国工作语言之一,是俄罗斯等多个国家的官方语言。随着“一带一路”倡议的推进和全球化进程的加快,俄语文本数据成为有关组织管理决策的重要信息来源,俄语文本挖掘也因而成为重要的管理决策支持方法。然而,俄语文本挖掘方法研究目前还远未成熟,尤其是其关键基础——俄语文本词语提取的性能较低,阻碍着俄语文本建模的准确性。因此,文章提出一种多策略融合的俄语文本词语提取方法,结合俄语词性分析、语法规则和串频统计等多种方法,自动提取包含单词和短语在内的俄语词语。在联合国平行语料库和Taiga Corpus语料库上的实验结果表明,文章提出的方法在保证高召回率的同时,达到了85%以上的高准确率,显著优于常用的ngram方法,能够为俄语文本主题发现和文本分/聚类等文本挖掘应用提供有效的词库。
关键词:俄语文本挖掘;词语提取;词性标注;频繁词串
中图分类号:G623.35;H08 文献标识码:A DOI:10.12339/j.issn.1673-8578.2021.03.009
Abstract:Russian is one of the working languages of the United Nations and the official language of many countries including Russia. With the advancement of the Belt and Road Initiative and the acceleration of globalization, Russian text data has become an important information resource for managerial decisionmaking of related organizations and Russian text mining has thus become a significant decisionmaking method. However, Russian text mining methods are still far away from being mature, especially the essential Russian text term extraction method, which affects the accuracy of Russian text modeling. This paper proposes a Russian text term extraction method, which combines multi strategies including Russian POS analysis, grammatical rules and string frequency statistics to automatically extract Russian words and multiword expressions. Experiments on the United Nations Parallel Corpus and the Taiga Corpus show that the proposed method achieves a high accuracy of approximate 85% which is much higher than normal recall rate, such as the ngram method. The proposed method can be used to create lexicons for Russian text mining applications such as text topic discovery, text classification, and text clustering.
Keywords: Russian text mining; term extraction; POS tag; frequent wordstring
收稿日期:2021-05-11
基金項目:国家自然科学基金项目“基于本体学习与本体映射的组织异构数据融合方法研究”(71771054)
引言
随着大数据时代的到来,数据尤其是文本数据呈现出爆炸式增长的态势,各个领域和组织都积极利用数据挖掘方法对所积累的数据进行分析。与此同时,“一带一路”倡议的推进和全球化进程的加快,使得单语言信息资源挖掘不能满足管理决策的需求,多种语言信息资源的挖掘逐渐成为实现全球知识发现和共享的关键技术。……
