大数据下MongoDB数据库档案文档存储去重研究
2015-11-17贺建英
贺建英
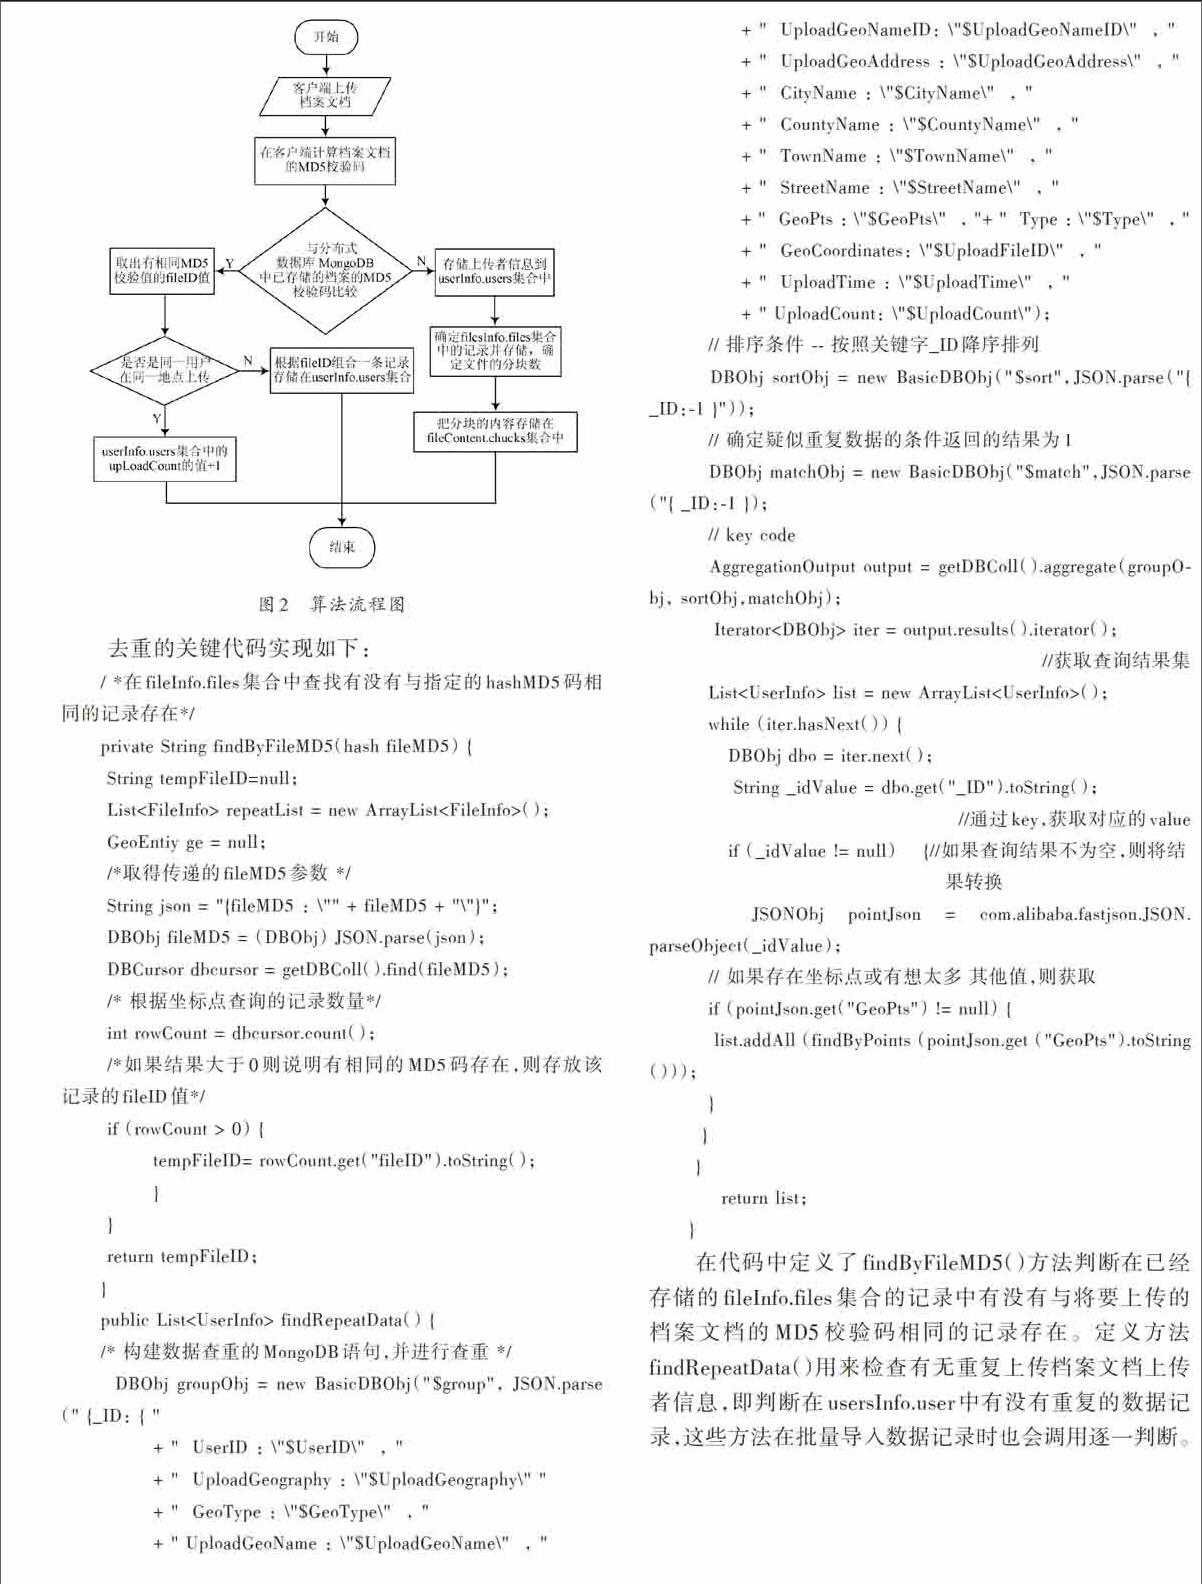
摘 要: 针对大数据下档案存储的现状,通过分析存储档案文档存在重复的原因,提出一种MongoDB存储档案文档的方法,利用MongoDB的GridFs统一处理不同类型和大小的文件,定义3个集合分别存储上传者记录、文件信息记录和分块文件内容,提出存储中通过文件MD5校验码值是否相同来进行去重研究,并实现去重的程序代码,有一定的实际意义。采用的分布式存储数据库增强了档案文档存储系统的可扩展性。实验表明,该方法能有效地去除重复的档案文档,提高查询效率。
关键词: MongoDB; MD5; 大数据; 档案文档去重; GridFs
中图分类号: TN911?34; TP311 文献标识码: A 文章编号: 1004?373X(2015)16?0051?05
Research on duplicated document removal in big data archive storage of MongoDB database
HE Jianying
(College of Computer, Sichuan University of Arts and Science, Dazhou 635000, China)
Abstract: In allusion to the present situation in document storage in case of big data, the MongoDB method to save documents is proposed according to the reason analysis of duplication in document storage. GridFs of MongoDB is used to store different type documents. Three different assemblages are definited to store the uploader record, document information record and content of blocked documents respectively. A research is proposed for removing the duplication by checking whether MD5 check code is same or not. It is significant to realize program code for duplicated document removal. The distributive memory database was used to enhance the expandability of the document saving system. The experimental result shows that this method can remove the duplicated documents effectively and improve the efficiency of inquiry.
Keywords: MongoDB; MD5; big data; file document duplicate removal; GridFs
0 引 言
随着信息技术的飞跃发展,各国各地都在大力发展电子政务建设。在此环境下档案局的档案文档也跨入了信息化存储的行列。但档案局的档案类型种类较多,除了纯文本的之外,还有图片、声音、视频、PDF等各种类型的文档,这些文档都是非结构化的数据,在传统的信息系统中,存放这些数据是比较困难的。因此在大数据环境下,设计信息化档案存储系统会首选非结构化的数据库,即NoSQL数据库。利用NoSQL家族中的MongoDB数据库作为存放档案文档的非结构化数据是较为理想的。MongoDB对存放大量的非结构化数据有很大的优势,但因MongoDB本身就是非结构化的,故在存放信息时会产生重复的数据。有人提出了像在关系数据库中一样建立关键索引来解决重复数据的问题,但在以文档方式存储的数据而言,当数据很大时,这种方式将会有弊端。……