基于LSTM?Attention神经网络的文本特征提取方法
2018-04-13赵勤鲁蔡晓东李波吕璐
赵勤鲁 蔡晓东 李波 吕璐
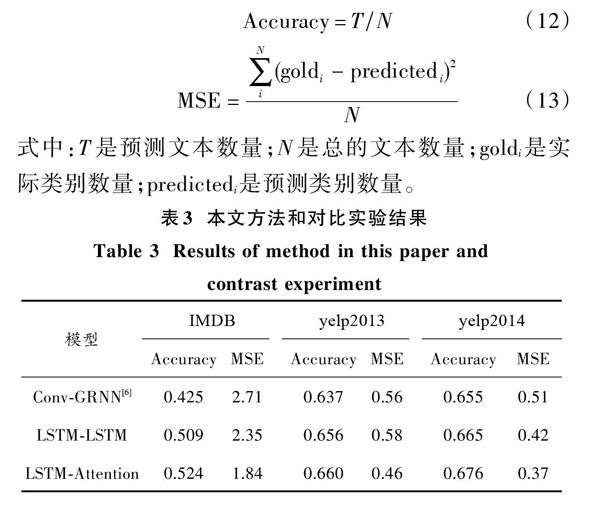
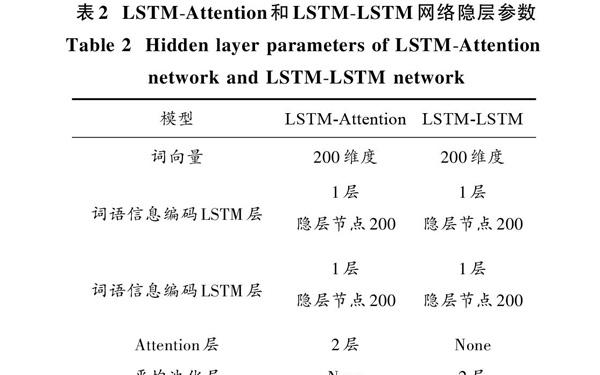
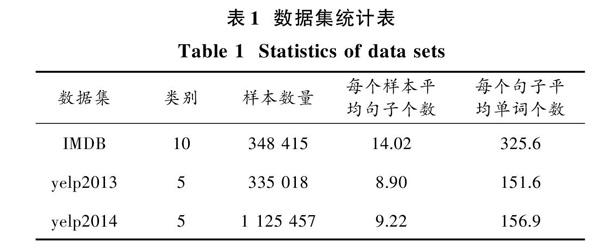
摘 要: 针对当前文本分类神经网络不能充分提取词语与词语和句子与句子之间的语义结构特征信息的问题,提出一种基于LSTM?Attention的神经网络实现文本特征提取的方法。首先,分别使用LSTM网络对文本的词语与词语和句子与句子的特征信息进行提取;其次,使用分层的注意力机制网络层分别对文本中重要的词语和句子进行选择;最后,将网络逐层提取得到的文本特征向量使用softmax分类器进行文本分类。实验结果表明,所提方法可以有效地提取文本的特征,使得准确率得到提高。将该方法应用在IMDB,yelp2013和yelp2014数据集上进行实验,分别得到52.4%,66.0%和67.6%的正确率。
关键词: LSTM?Attention; 注意力机制; 文本分类; 神经网络; 文本特征提取; softmax
中圖分类号: TN711?34; TP391.41 文献标识码: A 文章编号: 1004?373X(2018)08?0167?04
Abstract: In allusion to the problem that the current text classification neural network cannot fully extract semantic structural feature information among words or sentences, a text feature extraction method based on long short?term memory?attention (LSTM?Attention) neural network implementation is proposed. LSTM network is used to extract feature information among words or sentences of text. Network layer of hierarchical attention mechanism is used to select important words and sentences in text. Text classification is performed for the text feature vectors obtained from each network extraction by using softmax classifier. The experimental results show that the proposed method can effectively extract text features to improve the accuracy rate. When applying the method to the datasets of IMDB, yelp2013 and yelp2014 in the experiment, the correctness rates of 52.4%, 66.0% and 67.6% are obtained respectively.
Keywords: LSTM?Attention; attention mechanism; text classification; neural network; text feature extraction; softmax
0 引 言
文本分类任务是自然语言处理的一项基本任务,其目的是让文本得到相应的类别标签。文献[1]采用的词袋模型向量实现对文本特征的提取。这种方法分类效果的好坏受文本提取的特征影响较大,在训练时容易造成维度灾难。文献[2]是构建有效的文本特征以及建立文本情感词典来得到文本的类别特征。这样的方式耗费大量的人力并且效率低。随着深度学习在自然语言处理领域的发展,文献[3]使用卷积神经网络对文本单词级别的信息进行分类工作,通过卷积神经网络不同尺寸的卷积核来得到文本的N元特征信息进行文本特征分类。文献[4]使用卷积神经网络在字符级别对文本进行分类工作。……