基于Hadoop和Spark的可扩展性化工类大数据分析系统设计
2021-08-09尹旭熙
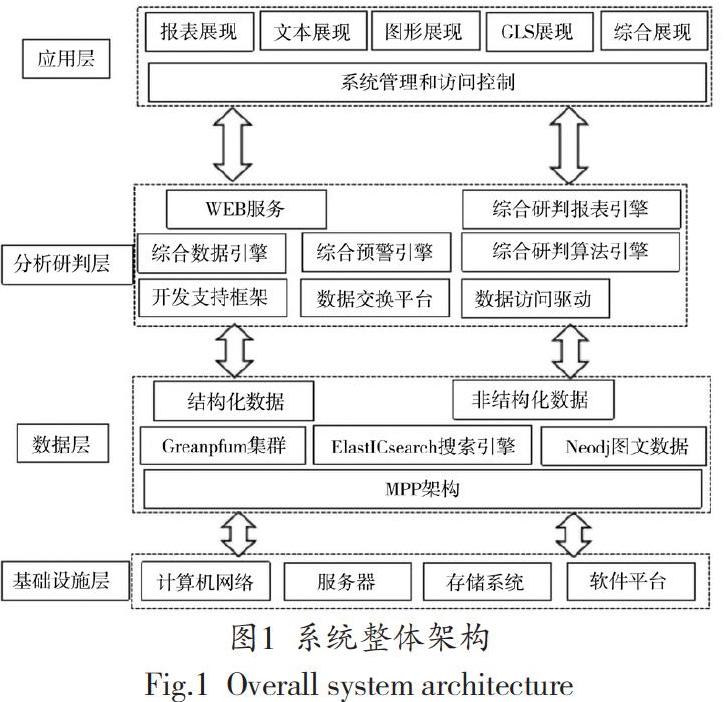
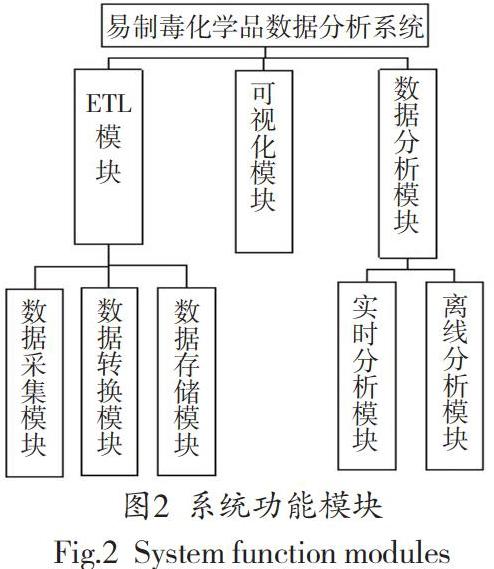
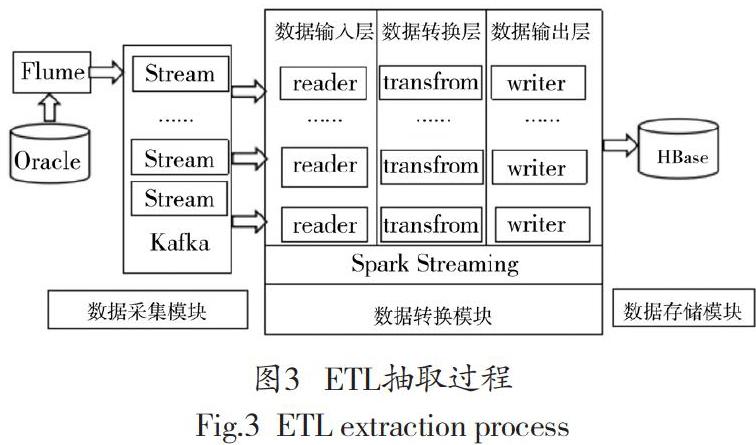
摘 要:针对易制毒化学品数据的海量增长问题,如何对这些数据进行分析,进而为易制毒化学品交易提供参考,是当前思考的重点。对此基于易制毒化学品海量增长的数据,结合Hadoop和Spark各自的优缺点,提出一种基于Hadoop+Spark的易制毒化学品数据分析系统。为实现该系统,首先采用Hadoop+Spark的框架对系统进行搭建;将系统功能模块分为数据分析模块、ETL模块、可视化模块3个主要模块,并对上述功能模块进行详细设计与实现;提出用于易制毒化学品价格预测的保序回归模型。最后搭建集群服务器和系统运行环境,运行上述预测模型,得到价格预测的误差值较小,能较准确预测易制毒化学品价格。
关键词:Hadoop框架;易制毒化学品;大数据分析;保序回归模型
中图分类号:TP311.13 文献标识码:A 文章编号:1001-5922(2021)06-0081-03
Abstract:In view of the massive growth of precursor chemicals data, how to analyze these data and provide reference for precursor chemicals trading is the focus of current thinking. Based on the huge growth data of precursor chemicals, combined with the advantages and disadvantages of Hadoop and Spark, a data analysis system of precursor chemicals based on Hadoop + Spark is proposed. In order to realize the system, Hadoop + Spark framework is used to build the system; the system function module is divided into three main modules: data analysis module, ETL module and visualization module, and the above functional modules are designed and implemented in detail; the ordinal regression model for price prediction of precursor chemicals is proposed. Finally, the cluster server and system operating environment are built, and the above prediction model is run. The error value of price prediction is small, which can accurately predict the price of precursor chemicals.
Key words:Hadoop framework; precursor chemicals; big data analysis; ordinal regression model
要想對易制毒化学品交易过程进行多角度、全方位的监控,就必须对相关数据进行实时分析处理,包括实时采集、数据流缓存、数据处理等环节,可是,现有研究主要关注于数据采集和数据处理等工作,反而忽略了数据清洗、数据缓存、数据布局等内容,这在一定程度上影响了实时数据的分析处理效率及效果。对此,一是基于Hadoop平台进行实时数据的分析处理。在实操中,利用HDFS系统进行数据储存,利用Map Reduce工具对实时数据进行快速处理,这为数据流的高效处置提供了技术支持。但HDFS对于实时数据流的适应性差,Map Reduce在分析实时数据流的过程中可能出现数据丢失、分析延迟等问题,导致Hadoop系统对于实时数据的处理效能不佳。……